The Stack Attack Surface: Why Your Modern Architecture Is Probably Leaking

The Beautiful Complexity Problem

Modern web applications are marvels of engineering. We’ve got React frontends talking to Node.js APIs, Docker containers orchestrated by Kubernetes, data flowing through Redis caches into PostgreSQL databases, all wrapped in AWS services and monitored by a constellation of observability tools. It’s elegant. It’s scalable. It’s also a security nightmare that would make a 1990s LAMP stack developer weep into their coffee.
The Stack Attack Surface: Why Your Modern Architecture Is Probably Leaking

The attack surface of a typical modern stack resembles a Swiss cheese factory after an earthquake. Every dependency, every service boundary, every configuration file represents a potential entry point. The days of securing a single Apache server with a firewall are as quaint as debugging with alert() statements. Today’s applications have more moving parts than a mechanical watch, and each tick represents another potential failure mode.

I’ve spent enough late nights investigating “impossible” security incidents to know that complexity isn’t just the enemy of maintainability. It’s the enemy of security. The more components in your stack, the more opportunities for something to go catastrophically wrong.
Illustration for The Stack Attack Surface: Why Your Modern Architecture Is Probably Leaking

The Dependency Cascade of Doom

Let’s talk about the elephant in the room: your package.json file probably has more third-party code than you wrote yourself. A typical Node.js project pulls in hundreds of dependencies, each with their own dependencies, creating a dependency tree that looks like a family reunion for a clan of rabbits. One malicious or compromised package anywhere in that tree can own your entire application.

The 2021 ua-parser-js incident perfectly illustrates this madness. A legitimate package with millions of weekly downloads suddenly started mining cryptocurrency and stealing passwords. The attack worked because developers had grown comfortable with the idea that npm install was basically safe. Spoiler alert: it’s not. When your build process automatically downloads and executes code from strangers on the internet, you’re essentially running a permanent bug bounty program for attackers.

Supply chain attacks aren’t exotic theoretical threats anymore. They’re Tuesday. The SolarWinds hack showed us that even the most paranoid organizations can be compromised through their dependencies. Your security is only as strong as the weakest link in your dependency chain, and that chain now includes packages maintained by burned-out volunteers who haven’t updated their SSH keys since Obama was president.

The real kicker? Most teams have no visibility into their transitive dependencies. They know they’re using Express, but they have no idea what Express depends on, or what those dependencies depend on. It’s dependencies all the way down, and somewhere in that turtle stack is a package that hasn’t been maintained since Harambe was alive.

Container Escape Artists and Orchestration Nightmares

Docker promised us isolation and reproducibility. What we got was a new attack surface with the subtlety of a brick through a window. Container escapes aren’t just possible, they’re practically inevitable when you’re running privileged containers or mounting the Docker socket inside containers. It’s like giving someone the keys to your house and acting surprised when they let themselves in.

The situation gets exponentially worse when you add Kubernetes to the mix. Kubernetes is a powerful orchestration platform that makes it easy to run containers at scale. It’s also a configuration nightmare that makes Apache’s httpd.conf look like a haiku. One misconfigured RBAC policy, one overly permissive service account, one forgotten debug endpoint, and suddenly your cluster is mining Bitcoin for someone in Eastern Europe.

I’ve seen production clusters where the default service account had cluster-admin privileges because “it was easier during development.” I’ve seen secrets mounted as environment variables that showed up in process lists. I’ve seen init containers with root access that downloaded and executed shell scripts from public GitHub repos. Each of these decisions made perfect sense to someone at the time, which is the truly terrifying part.

The principle of least privilege isn’t optional in containerized environments. It’s the difference between a contained breach and a complete cluster takeover. Yet most teams treat Kubernetes security like they treat flossing: something they know they should do but somehow never get around to.

The API Gateway Wild West

Modern applications are API-first, which sounds sophisticated until you realize that every API endpoint is a potential entry point for an attacker. Your sleek GraphQL API that can query any field on any object? Congratulations, you’ve just built a data exfiltration tool that comes with its own query language. Your REST API with its clean resource-based URLs? Each endpoint is a door, and some of those doors don’t have locks.

Rate limiting is the security equivalent of hoping really hard that bad things won’t happen. Most teams implement it as an afterthought, setting generous limits that wouldn’t stop a determined toddler with a script. I’ve seen APIs that would happily serve gigabytes of data to anyone who asked nicely. Authentication is often implemented as a checkbox feature rather than a fundamental architectural concern.

The real fun begins when you start chaining microservices together. Service A calls Service B, which calls Service C, and somewhere in that chain, someone forgot to validate inputs or check permissions. The blast radius of a vulnerability in one service can cascade through your entire system like a security avalanche. East-west traffic in service meshes often has all the security rigor of a backyard barbecue.

API versioning adds another layer of complexity. You’ve got v1 endpoints that should have been deprecated years ago, v2 endpoints that were rushed to production, and v3 endpoints that exist only in documentation. Each version has its own security characteristics, and attackers love nothing more than finding the one old endpoint that still accepts XML input and doesn’t validate schemas.

The Infrastructure as Code Irony

Infrastructure as Code was supposed to make our deployments more secure and reproducible. Instead, we’ve managed to version control our security misconfigurations. Your Terraform files are now a permanent record of every time someone decided that opening port 22 to the world was “just temporary” or that storing database passwords in plain text was “good enough for now.”

Cloud provider security is a shared responsibility model, which in practice means that when something goes wrong, both you and your cloud provider will point at each other until the lawyers get involved. The cloud provider secures the infrastructure, you secure everything you put on it. This division of labor works great until you realize that “everything you put on it” includes IAM policies written by developers who think S3 bucket policies are suggestions rather than law.

The default settings for most cloud services prioritize ease of use over security, which makes sense from a business perspective but creates a minefield for operations teams. Public S3 buckets, overly permissive security groups, database instances accessible from the internet. These aren’t edge cases, they’re Tuesday morning incident reports.

Configuration drift is the silent killer of infrastructure security. Your Terraform state says one thing, your actual infrastructure says another, and the difference between them is usually where the vulnerabilities hide. Immutable infrastructure sounds great in theory, but in practice, someone always needs to SSH into that box to check one quick thing, and that one quick thing becomes a permanent backdoor.

If you’ve made it this far, you’re either deeply committed to security or you enjoy reading about controlled disasters. Either way, I’d love to hear about your own stack security adventures. What’s the most creative vulnerability you’ve discovered in your own systems? Drop me a line and let’s compare war stories.
How Prometheus Nearly Broke My Team (And Why We Still Love It)

The Metrics Gold Rush of 2019

Four years ago, our engineering team was drowning in alert fatigue. Our homegrown monitoring system sent us 847 Slack notifications in a single Tuesday. Not alerts about actual problems. Just noise. The kind of noise that makes you turn off notifications and pray nothing important breaks during your lunch.

How Prometheus Nearly Broke My Team (And Why We Still Love It)

Enter Prometheus, the darling of the CNCF ecosystem. Everyone was talking about it. Pull-based metrics. Service discovery. PromQL queries that made SQL look friendly. We figured if it was good enough for SoundCloud and later became a CNCF graduated project, it had to be our salvation.

Spoiler alert: implementing Prometheus correctly is like learning to drive a Formula 1 car by reading the manual. Technically possible, but you’re going to hit some walls first.

Illustration for How Prometheus Nearly Broke My Team (And Why We Still Love It)

The Reality Check Nobody Warns You About

Week one went smoothly. Too smoothly. We instrumented our Go services with the official client library, spun up a Prometheus server, and watched beautiful time series data populate our new Grafana dashboards. Management loved the pretty graphs. We felt like monitoring heroes.

Week three is when Prometheus taught us about cardinality the hard way. One well-meaning developer added user IDs as metric labels. Suddenly our Prometheus server was consuming 32GB of RAM and falling behind on scrapes. The irony of our monitoring system needing monitoring was not lost on us.

The real lesson hit during a 2 AM incident. Our primary service was responding slowly, but our dashboards showed everything green. We had configured our scrape intervals wrong, set our recording rules incorrectly, and our alerting rules had more holes than a block of Swiss cheese. We were flying blind with the most sophisticated instrument panel in the industry.

What the Documentation Doesn’t Tell You

Prometheus documentation is thorough but assumes you already understand distributed systems monitoring. It’s like a cookbook that starts with “first, catch a fish” without explaining how boats work.

Here’s what took us six months to learn: metric naming matters more than you think. We started with names like “api_request_count” and ended up refactoring to “myapp_http_requests_total” when we realized we needed proper namespacing. The Prometheus naming conventions aren’t suggestions. They’re survival tactics for when you have 50 services and 10,000 metrics.

Storage became our next education. Prometheus stores everything locally by default. Great for simplicity, terrible for production where servers restart, disks fill up, and data mysteriously vanishes. We learned about remote storage the expensive way when three months of metrics disappeared during a botched upgrade. Thanos became our new best friend, though setting up object storage integration felt like building IKEA furniture without the pictures.

The real breakthrough came when we stopped treating Prometheus like a traditional monitoring system. It’s not New Relic. It’s not DataDog. It’s a time series database with opinions, and those opinions will reshape how you think about observability.

The Moments When Everything Clicked

Six months in, something magical happened. A junior engineer wrote a PromQL query that tracked the 95th percentile latency by service endpoint, filtered by region, aggregated over 5-minute windows. She did it in fifteen minutes. That same query in our old system would have required a database schema change and a deployment.

The service discovery features finally made sense when we migrated to Kubernetes. Prometheus automatically discovered new pods, scraped their metrics, and updated our dashboards without any manual configuration. Watching it adapt to our scaling events felt like watching a good science fiction movie. The future had arrived, and it was pull-based.

Our alerting transformed from reactive noise to proactive intelligence. Instead of alerting on symptoms, we started alerting on leading indicators. Memory pressure before OOM kills. Request queue depth before response time degradation. Error rate increases before customer complaints. We went from fixing problems to preventing them.

The ecosystem integration surprised us too. Prometheus plays nicely with everything. Jaeger for tracing, Fluentd for logs, Grafana for visualization, Alert Manager for notifications. Each tool does one thing well, and they compose beautifully. It’s Unix philosophy for the cloud native era.

Lessons From the Trenches

After three years running Prometheus in production, here’s what actually matters. Start small. Instrument one service properly before trying to monitor everything. Focus on the four golden signals: latency, traffic, errors, and saturation. Everything else can wait.

Invest in proper labeling strategy upfront. Cardinality explosions are real, and they will murder your Prometheus server without mercy. Keep labels to essential dimensions. User IDs are not essential dimensions.

Learn PromQL gradually, but learn it well. It’s weird syntax that looks like SQL’s angry cousin, but it’s incredibly powerful once it clicks. The histogram and summary metric types seem confusing initially but become indispensable for percentile calculations.

Plan for scale early. Federation, remote storage, and high availability aren’t luxury features. They’re requirements for anything beyond a toy deployment. Thanos or Cortex aren’t optional if you care about your data.

Most importantly, remember that Prometheus is infrastructure, not a product. You’re not buying monitoring. You’re building monitoring. The flexibility is incredible, but it comes with operational overhead that your team needs to embrace.

We’re still running Prometheus four years later. Our alert fatigue is gone, our incident response is faster, and our system understanding is deeper. It nearly broke us, but it also made us better engineers. If you’re considering the jump, buckle up. It’s worth the ride, but pack some patience and maybe a good book on time series analysis.

The Debugging Toolkit Nobody Talks About: Distributed Tracing for the Rest of Us

Why Your Current Debugging Strategy Is Probably Broken

Let me guess. Your distributed system is acting up again, and you’re staring at seventeen different dashboards trying to piece together what happened when service A called service B, which then made three calls to service C, and somewhere in that chain everything went sideways. You’ve got logs scattered across multiple services, metrics that don’t quite align on timestamps, and that sinking feeling that you’re missing something important.

The Debugging Toolkit Nobody Talks About: Distributed Tracing for the Rest of Us

This is the distributed systems debugging nightmare that keeps senior engineers awake at night. Not because the problems are unsolvable, but because the traditional debugging tools we learned on monoliths just don’t work when your application is spread across dozens of services, containers, and cloud regions. The request that’s failing might touch eight different services, and good luck reconstructing that call graph from grep and prayer.

Here’s the thing though: there’s a category of tools that’s been quietly changing how we debug distributed systems, and most teams are still sleeping on them. Distributed tracing isn’t new, but the way modern tools implement it is finally making it accessible for teams that aren’t Google or Netflix.

Illustration for The Debugging Toolkit Nobody Talks About: Distributed Tracing for the Rest of Us

Distributed Tracing: The Game Changer You Haven’t Adopted Yet

Distributed tracing is like having a GPS tracker for every request flowing through your system. Instead of trying to correlate timestamps across log files like some kind of digital archaeologist, you get a complete visual map of exactly what happened, when, and where things went wrong. Each request gets a unique trace ID that follows it through every service call, database query, and external API interaction.

The magic happens when you can see the entire request flow in a single view. That mysterious 500ms latency spike? It’s right there in the trace, showing you that your authentication service is making an unnecessary round trip to Redis for data it already cached. That intermittent failure that only happens on Tuesdays? The trace reveals it’s a race condition in your payment processing pipeline that only triggers under specific load conditions.

What makes modern distributed tracing tools particularly appealing is how they’ve solved the adoption barrier. Early tracing solutions required massive infrastructure changes and vendor lock-in that made CTOs break out in cold sweats. Today’s tools use OpenTelemetry standards and can be adopted gradually, service by service. You can start with your most critical service and expand from there, which is exactly how you should approach any infrastructure change that involves the words “distributed” and “system.”

The Tools That Are Actually Worth Your Time

Jaeger deserves the top spot here because it’s open source, battle-tested, and doesn’t require you to mortgage your engineering budget. Originally developed by Uber, Jaeger handles the collection, storage, and visualization of traces with a clean interface that won’t make your eyes bleed. The setup is straightforward enough that you can have it running in your development environment in an afternoon, which is more than I can say for most distributed systems tools.

Honeycomb takes a different approach that’s particularly powerful for complex debugging scenarios. Instead of just showing you traces, it lets you slice and dice the data to answer questions like “show me all traces where the database query took longer than 100ms AND the user was on a mobile device AND it happened during peak traffic.” This kind of exploratory debugging capability is invaluable when you’re hunting down those edge cases that only show up under specific conditions.

For teams already invested in the Elastic ecosystem, APM tools like Elastic APM provide distributed tracing alongside your existing logging and monitoring infrastructure. The integration story here is appealing because you can correlate traces with logs and metrics in a single interface. Plus, if you’re already running Elasticsearch for log aggregation, the operational overhead is minimal.

Zipkin rounds out the list as another solid open source option that’s particularly well-suited for teams that want something lightweight and focused. It doesn’t have all the bells and whistles of commercial solutions, but it excels at the core tracing functionality and integrates well with existing monitoring stacks.

Implementation Strategies That Don’t Break Everything

The biggest mistake teams make with distributed tracing is trying to instrument everything at once. This inevitably leads to performance concerns, alert fatigue, and the kind of project scope creep that makes seasoned engineers update their LinkedIn profiles. Start small and focus on your most important request paths first.

Pick one service that’s either giving you the most trouble or handles your most important business logic. Instrument it thoroughly, get comfortable with the data, and then expand to upstream and downstream services. This approach lets you build confidence in the tooling while delivering immediate value. You’ll be amazed how much insight you can gain just from tracing a single service, especially once you start seeing how external dependencies affect your performance.

Sampling matters for production deployments. Tracing every single request is a great way to create more problems than you solve, both from a performance and cost perspective. Most teams find that sampling 1-5% of requests gives them sufficient data for debugging while keeping overhead reasonable. Smart sampling strategies can increase this percentage for error conditions or high-value user sessions.

Don’t forget about instrumentation libraries and auto-instrumentation tools. Modern tracing frameworks can automatically instrument common libraries and frameworks with minimal code changes. This is particularly valuable for languages like Java and .NET where the ecosystem has mature auto-instrumentation capabilities.

The Real-World Impact

I’ve seen distributed tracing turn week-long debugging sessions into hour-long investigations. The ability to see exactly where a request spent its time eliminates the guesswork that dominates traditional distributed systems debugging. When someone reports that “the checkout flow is slow,” you can immediately see whether the slowdown is in payment processing, inventory checks, or that new recommendation engine that seemed like a good idea six months ago.

The debugging velocity improvement is just the beginning though. Distributed tracing fundamentally changes how you think about system architecture and performance optimization. When you can see the actual request flow through your services, architectural decisions become data-driven rather than opinion-driven. That debate about whether to break up the monolith gets a lot more productive when you have concrete data about service interaction patterns.

The operational benefits extend beyond debugging too. Distributed traces provide invaluable data for capacity planning, SLA monitoring, and performance testing. You can identify bottlenecks before they become customer-facing issues and optimize resource allocation based on actual usage patterns rather than theoretical load models.

If you’re still debugging distributed systems the hard way, it’s time to level up your toolkit. Start with Jaeger if you want something proven and open source, or try Honeycomb if you need more sophisticated analysis capabilities. Your future self, debugging production issues at 3 AM, will thank you for making the investment in proper observability tooling.

The API That Made Me Question Everything I Knew About REST

When Your Perfect API Becomes Everyone’s Nightmare

Three years ago, I shipped what I thought was a beautifully designed REST API. Clean endpoints, proper HTTP verbs, sensible resource naming. Six months later, our mobile team was making 47 separate API calls to render a single screen. The frontend developers had built a caching layer so complex it had its own caching layer. I learned something that day: textbook REST and real-world usability don’t always shake hands.

That API taught me more about design patterns than any conference talk ever could. The patterns that actually matter aren’t the ones that look good on architectural diagrams. They’re the ones that prevent your colleagues from plotting your demise during code reviews.

The Resource Composition Pattern That Saved My Sanity

After watching our mobile app struggle with waterfall requests, I implemented what I now call the “kitchen sink” pattern. Instead of forcing clients to assemble data from multiple endpoints, we created composite resources. Our `/user/profile` endpoint started returning not just user data, but their recent posts, notification preferences, and friend suggestions in a single response.

The pattern is simple: identify the common data access patterns your clients actually use, then build endpoints that fit those patterns directly. Yes, it violates pure REST principles. No, I don’t care anymore. When your API response time drops from 3 seconds to 400 milliseconds because you eliminated 12 round trips, philosophical purity takes a backseat to user experience.

We implemented this using a query parameter system where clients could specify what related data they needed. `GET /users/123?include=posts,preferences,friends` became our Swiss Army knife. The backend complexity increased, but the client-side code became refreshingly simple.

Version Your Schema, Not Your Endpoints

I used to version APIs the “proper” way: `/v1/users`, `/v2/users`, `/v3/users`. Then I worked at a company where we had 17 different API versions in production simultaneously. Maintaining that nightmare taught me that endpoint versioning is often a symptom of poor schema design.

The better pattern is schema evolution with backward compatibility. Add fields freely, but never remove them without a deprecation cycle. Use nullable fields for new optional data. When you absolutely must break compatibility, version individual fields within the same endpoint structure rather than creating entirely new endpoints.

We implemented this using a `fields` parameter system similar to GraphQL field selection. Clients could request specific schema versions for individual fields: `GET /users/123?fields=name,email,profile.v2`. This let us evolve our API step by step without forcing mass migrations across consuming applications.

Error Handling That Doesn’t Make Developers Cry

Nothing exposes poor API design like error scenarios. I’ve seen APIs return HTTP 200 with error messages buried in the response body. I’ve debugged issues where the same business logic failure returned different status codes depending on which internal service triggered it. These experiences taught me that consistent error handling isn’t just nice to have. It’s the difference between a usable API and a support ticket generator.

The pattern that works: standardize your error response structure and stick to it religiously. Every error response should include a human-readable message, a machine-readable error code, and enough context for debugging. We settled on a structure like `{“error”: {“code”: “INVALID_EMAIL”, “message”: “Email address must be valid”, “details”: {“field”: “email”, “provided”: “not-an-email”}}}`. Verbose? Yes. Debuggable? Absolutely.

More importantly, map your business logic errors to HTTP status codes consistently. We created an error registry where each business error had a predetermined HTTP status. No more guessing whether validation failures should return 400 or 422. The API became predictable, and our integration tests became much simpler to write.

Pagination That Scales Beyond Your Wildest Dreams

Offset-based pagination seems logical until you’re dealing with real-world data that changes while users browse. I learned this lesson when users complained about seeing duplicate items in paginated lists. The problem: our `LIMIT 20 OFFSET 100` approach broke down when new records were inserted at the beginning of the dataset.

Cursor-based pagination solved this elegantly. Instead of page numbers, each response includes opaque cursors that represent positions in the dataset. `GET /posts?after=eyJpZCI6MTIzNDU2fQ` returns results after a specific cursor position, regardless of concurrent data changes. The implementation requires a bit more thought upfront, but it scales to massive datasets and handles real-time updates gracefully.

We enhanced this with metadata that clients actually found useful: `{“data”: […], “pagination”: {“next_cursor”: “…”, “has_more”: true, “estimated_total”: 1500}}`. The estimated total helped with UI decisions, while the boolean flag eliminated guesswork about whether more data existed.

The Patterns That Actually Matter

These patterns came from real problems, not academic exercises. The composition pattern solved performance issues that were driving users away. Schema evolution prevented version mess that was consuming our development cycles. Standardized error handling reduced support tickets and integration time.

The best API design pattern is the one that makes your colleagues’ lives easier. Sometimes that means abandoning textbook approaches for pragmatic solutions. The goal isn’t to build the most theoretically correct API. It’s to build one that works reliably in production and doesn’t make other developers question their career choices.

What patterns have you discovered in the trenches that didn’t make it into the design books?

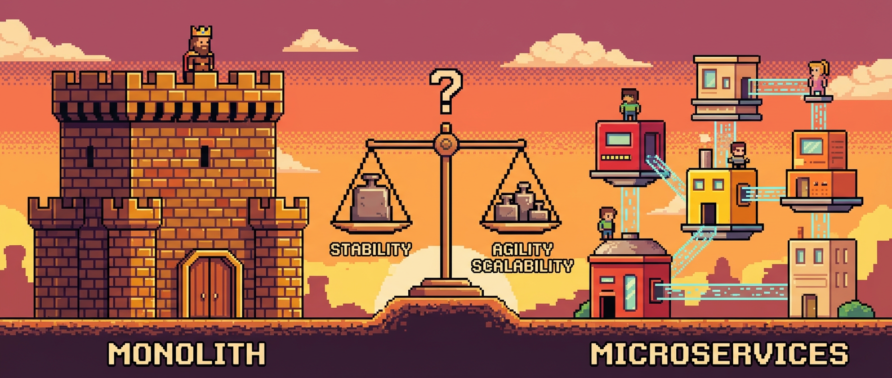
The Monolith vs Microservices Decision Tree: A Field Guide to Not Shooting Yourself in the Foot

The Industry’s Collective Amnesia Problem

Every few years, our industry rediscovers the truth that distributed systems are hard. We package this revelation in new terminology, write excited blog posts about our architectural awakening, then watch the next wave of engineers make identical mistakes with fresh enthusiasm. Right now, we’re deep in the microservices cycle, where teams that couldn’t properly deploy a single Rails app are confidently orchestrating dozens of services across Kubernetes clusters.

The Monolith vs Microservices Decision Tree: A Field Guide to Not Shooting Yourself in the Foot

The pendulum swings predictably. Monoliths become legacy nightmares that “don’t scale.” Microservices become the silver bullet until teams discover that network calls fail, transactions span service boundaries poorly, and debugging a request that touches twelve services makes you question your life choices. Then someone writes a post about how Shopify handles millions of requests from a monolith, and suddenly everyone’s talking about “modular monoliths” like it’s a revolutionary concept.

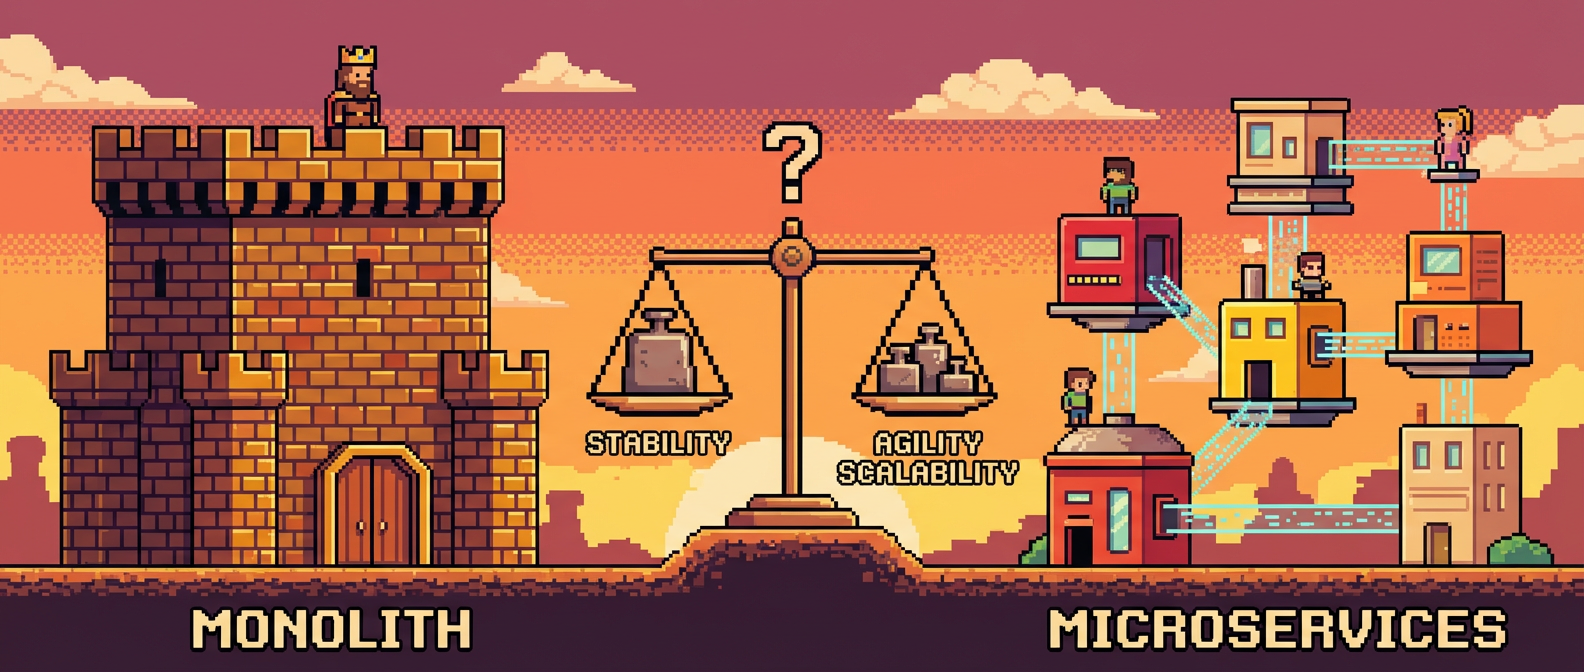
Here’s the uncomfortable truth: both architectures work brilliantly when applied correctly, and both fail spectacularly when copied without understanding the underlying trade-offs. The real skill isn’t picking the trendy option. It’s knowing which problems each approach solves and which new problems it creates.

Illustration for The Monolith vs Microservices Decision Tree: A Field Guide to Not Shooting Yourself in the Foot

When Monoliths Actually Win

Monoliths get a bad rap because most examples people cite are decade-old PHP applications held together with prayer and technical debt. But a well-designed monolith is beautiful. You get ACID transactions across your entire business logic. Your IDE understands the complete call graph. When something breaks at 3 AM, you have exactly one place to look for logs.

The performance characteristics alone should make you pause before reaching for microservices. In-process function calls measured in nanoseconds versus network calls measured in milliseconds. No serialization overhead. No service discovery. No distributed tracing complexity. Your laptop can run the entire application stack, which means your junior developers can actually contribute without spending three weeks configuring their local environment.

I’ve watched teams with legitimate scale needs choose monoliths and thrive. One e-commerce platform I worked with handles tens of thousands of orders per minute from a single Rails application. Their secret? They understood their bottlenecks. Database queries, not service boundaries. Caching strategies, not container orchestration. They invested in profiling tools and database optimization instead of service meshes and API gateways.

The dirty secret of monolith scalability is that most applications never hit the limits. Your “web scale” problems probably aren’t web scale. Your team of eight engineers building a B2B SaaS application doesn’t need the same architecture as Netflix. But somehow, we’ve convinced ourselves that if we don’t start with microservices, we’ll never be able to handle growth.

The Microservices Sweet Spot

Microservices shine when you have genuine organizational scale, not just technical scale. Conway’s Law isn’t a suggestion, it’s physics. If you have 200 engineers across 15 teams, a single codebase becomes a coordination nightmare. Pull requests stack up. Deployments require extensive cross-team planning. Feature velocity drops as teams step on each other’s changes.

The magic happens when service boundaries align with team boundaries. Each team owns their domain completely: the data model, the business logic, the deployment pipeline, and the operational responsibilities. This ownership model scales because it reduces coordination overhead. Teams can move independently as long as they honor their API contracts.

But here’s where most organizations get it wrong: they adopt microservices for technical reasons while keeping monolithic team structures. You end up with the worst of both worlds. All the complexity of distributed systems with none of the organizational benefits. Teams still need to coordinate changes across multiple services they don’t own. Debugging requires tribal knowledge about which team owns which service.

The technical benefits are real but secondary. Independent deployments mean you can release critical bug fixes without waiting for other teams’ changes. Technology diversity lets teams choose the right tool for their specific problems. Fault isolation contains failures to individual services rather than taking down the entire platform. These advantages matter, but only if your organization can actually use them.

The Hidden Costs Nobody Talks About

Microservices advocates love to discuss the benefits while handwaving away the operational complexity. Let me paint you a picture of what “production ready” microservices actually require. You need service discovery so services can find each other. Circuit breakers to handle cascading failures. Distributed tracing to debug requests that span multiple services. Centralized logging to correlate events across your architecture.

Your monitoring story explodes in complexity. Instead of watching one application, you’re monitoring dozens of services, each with their own health checks, metrics, and alerting thresholds. Your deployment pipeline needs to handle service dependencies and coordinate rolling updates. Your database strategy becomes a graduate-level course in distributed systems theory.

Then there’s the performance death by a thousand cuts. Each service boundary introduces network latency. JSON serialization overhead accumulates across service calls. Database connections multiply as each service maintains its own connection pool. What started as a single database query becomes a distributed join across multiple services, each adding milliseconds to your response time.

The debugging experience deserves special mention. In a monolith, you set a breakpoint and step through the code. In microservices, you correlate trace IDs across service logs, hoping someone remembered to propagate the correlation context correctly. Error messages become archaeological expeditions as you piece together the failure chain from scattered log entries.

Making the Decision That Actually Makes Sense

The choice between monoliths and microservices isn’t about technical superiority. It’s about matching your architecture to your constraints. Start with your team structure, not your technical requirements. If you have fewer than 20 engineers, microservices are probably premature optimization. You don’t have enough people to properly own multiple services.

Consider your operational maturity honestly. Can your team deploy applications reliably? Do you have proper monitoring and alerting? Can you debug production issues effectively? If you’re still figuring out the basics with a monolith, adding distributed systems complexity won’t help.

Think about your actual scale requirements, not your hypothetical ones. Are you CPU bound? Memory bound? Database bound? Network bound? Most applications hit database limits long before they need horizontal scaling. A well-tuned monolith with read replicas and caching often outperforms a poorly designed microservices architecture.

The best approach I’ve seen is evolutionary. Start with a modular monolith that clearly defines internal boundaries. When specific modules genuinely need independent scaling or different technology stacks, extract them as services. This gives you the organizational benefits of clear ownership while avoiding premature distribution.

Both architectures are tools, not religions. The teams that succeed are the ones that choose based on their actual constraints rather than industry trends. They understand that elegant solutions come from matching the tool to the problem, not from following the architectural fashion of the week.

What’s your experience been with these architectural decisions? I’m always curious to hear about teams that bucked conventional wisdom and found success, whether that’s scaling monoliths beyond what the experts said was possible or making microservices work with smaller teams through creative organizational approaches.